| Date |
Topic |
Instructor |
Scriber |
| 09/07/2026, Mon |
Lecture 01: A Historic Overview of AI and Statistical Machine Learning. [ slides (pdf) ]
|
Y.Y. |
|
| 09/14/2026, Mon |
Lecture 02: Supervised Learning: linear regression and classification [ slides ]
|
Y.Y. |
|
| 09/21/2026, Mon |
Lecture 03: Model Assessment and Selection: Subset, Ridge, Lasso, and PCR [ slides ] and Project 1 [ pdf ]
[Reference]:
- To view .ipynb files below, you may try [ Jupyter NBViewer]
- Python Notebook for Model Selection (Subset, Ridge, Lasso, and Principal Component Regression)
[ Selection.ipynb ]
- Kaggle: Home Credit Default Risk [ link ]
- Kaggle: M5 Forecasting - Accuracy, Estimate the unit sales of Walmart retail goods.
[ link ]
|
Y.Y. |
|
| 09/28/2026, Mon |
Lecture 04: Moving beyond Linearity [ slides ]
[ Seminar ]
- Title: A Statistical View on Implicit Regularization: Gradient Descent Dominates Ridge [ slides ][ link ]
- Speaker: Dr. Jingfeng WU, UC Berkeley
- Abstract: A key puzzle in deep learning is how simple gradient methods find generalizable solutions without explicit regularization. This talk discusses the implicit regularization of gradient descent (GD) through the lens of statistical dominance. Using linear regression as a clean proxy, we present three surprising findings.
First, GD dominates ridge regression: with comparable regularization, the excess risk of GD is always within a constant factor of ridge, but ridge can be polynomially worse even when tuned optimally. Second, GD is incomparable with online stochastic gradient descent (SGD). While it is known that for certain problems GD can be polynomially better than SGD, the reverse is also true: we construct problems, inspired by benign overfitting theory, where optimally stopped GD is polynomially worse. Finally, GD dominates SGD for a significant subclass of problems -- those with fast and continuously decaying covariance spectra -- which includes all problems satisfying the standard capacity condition.
This is joint work with Peter Bartlett, Sham Kakade, Jason Lee, and Bin Yu.
- Bio:
Jingfeng Wu is an assistant professor of Statistics at UC Berkeley. His research focuses on deep learning theory, optimization, and statistical learning. He earned his Ph.D. in Computer Science from Johns Hopkins University in 2023. Prior to that, he received a B.S. in Mathematics (2016) and an M.S. in Applied Mathematics (2019), both from Peking University. In 2023, he was recognized as a Rising Star in Data Science by the University of Chicago and UC San Diego.
[Reference]:
- Daniel Soudry, Elad Hoffer, Mor Shpigel Nacson, Suriya Gunasekar, Nathan Srebro. The Implicit Bias of Gradient Descent on Separable Data.
[ arXiv:1710.10345 ]. ICLR 2018. Gradient descent on logistic regression leads to max margin.
- Matus Telgarsky. Margins, Shrinkage, and Boosting. [ arXiv:1303.4172 ]. ICML 2013. An older paper on gradient descent on exponential/logistic loss
leads to max margin.
- Yuan Yao, Lorenzo Rosasco and Andrea Caponnetto. On Early Stopping in Gradient Descent Learning. Constructive Approximation, 2007, 26 (2): 289-315.
[ link ]
- Jingfeng Wu, Peter L. Bartlett, Jason D. Lee, Sham M. Kakade, and Bin Yu. Risk Comparisons in Linear Regression: Implicit Regularization Dominates Explicit Regularization. [ arXiv:2509.17251 ]
|
Y.Y. |
|
| 10/05/2026, Mon |
Lecture 05: Decision Tree, Bagging, Random Forests and Boosting [ YY's slides ]
|
Y.Y. |
|
| 10/12/2026, Mon |
Lecture 06: Support Vector Machines [ YY's slides ]
[ Project 1 Presentation ]:
- M5 Accuracy: Group 13 (YANG Chutong, CHEN Meihan), Group 3 (GAO Jiashen, LIU Haoran), Group 6 (CHEN Xujun, YI Youkang, WU Yutong)
-
Credit Default: Group 5 (PENG Ziyue), Group 18 (HU Boyi, WANG Haoran, CHEN Mohan, YANG Junxi)
- Kaggle: Home Credit Default Risk [ link ]
- Kaggle: M5 Forecasting - Accuracy, Estimate the unit sales of Walmart retail goods.
[ link ]
|
Y.Y. |
|
| 10/26/2026, Mon |
Lecture 07: An Introduction to Convolutional Neural Networks [ YY's slides ]
|
Y.Y. |
|
| 11/02/2026, Mon |
Lecture 08: An Introduction to Recurrent Neural Networks (RNN), Long Short Term Memory (LSTM), Attention and Transformer [ slides ]
|
Y.Y. |
|
| 11/09/2026, Mon |
Lecture 09: Transformer and Applications [ slides ] and Final Project Initialization [ project2.pdf ]
[ Kaggle Contests ]:
- Kaggle: Home Credit Default Risk [ link ]
- Kaggle: M5 Forecasting - Accuracy, Estimate the unit sales of Walmart retail goods.
[ link ]
- Kaggle: M5 Forecasting - Uncertainty, Estimate the uncertainty distribution of Walmart unit sales.
[ link ]
- Kaggle: Ubiquant Market Prediction - Make predictions against future market data.
[ link ]
- Kaggle: G-Research Crypto Forecasting.
[ link ]
[Paper Replication]:
- Shihao Gu, Bryan Kelly and Dacheng Xiu
"Empirical Asset Pricing via Machine Learning", Review of Financial Studies, Vol. 33, Issue 5, 2020, 2223-2273. Winner of the 2018 Swiss Finance Institute Outstanding Paper Award.
[ link ]
- Jingwen Jiang, Bryan Kelly and Dacheng Xiu
"(Re-)Imag(in)ing Price Trends", The Journal of Finance, 78: 3193-3249, 2023.
[ ssrn ][ https://doi.org/10.1111/jofi.13268 ]
[ Seminar ]
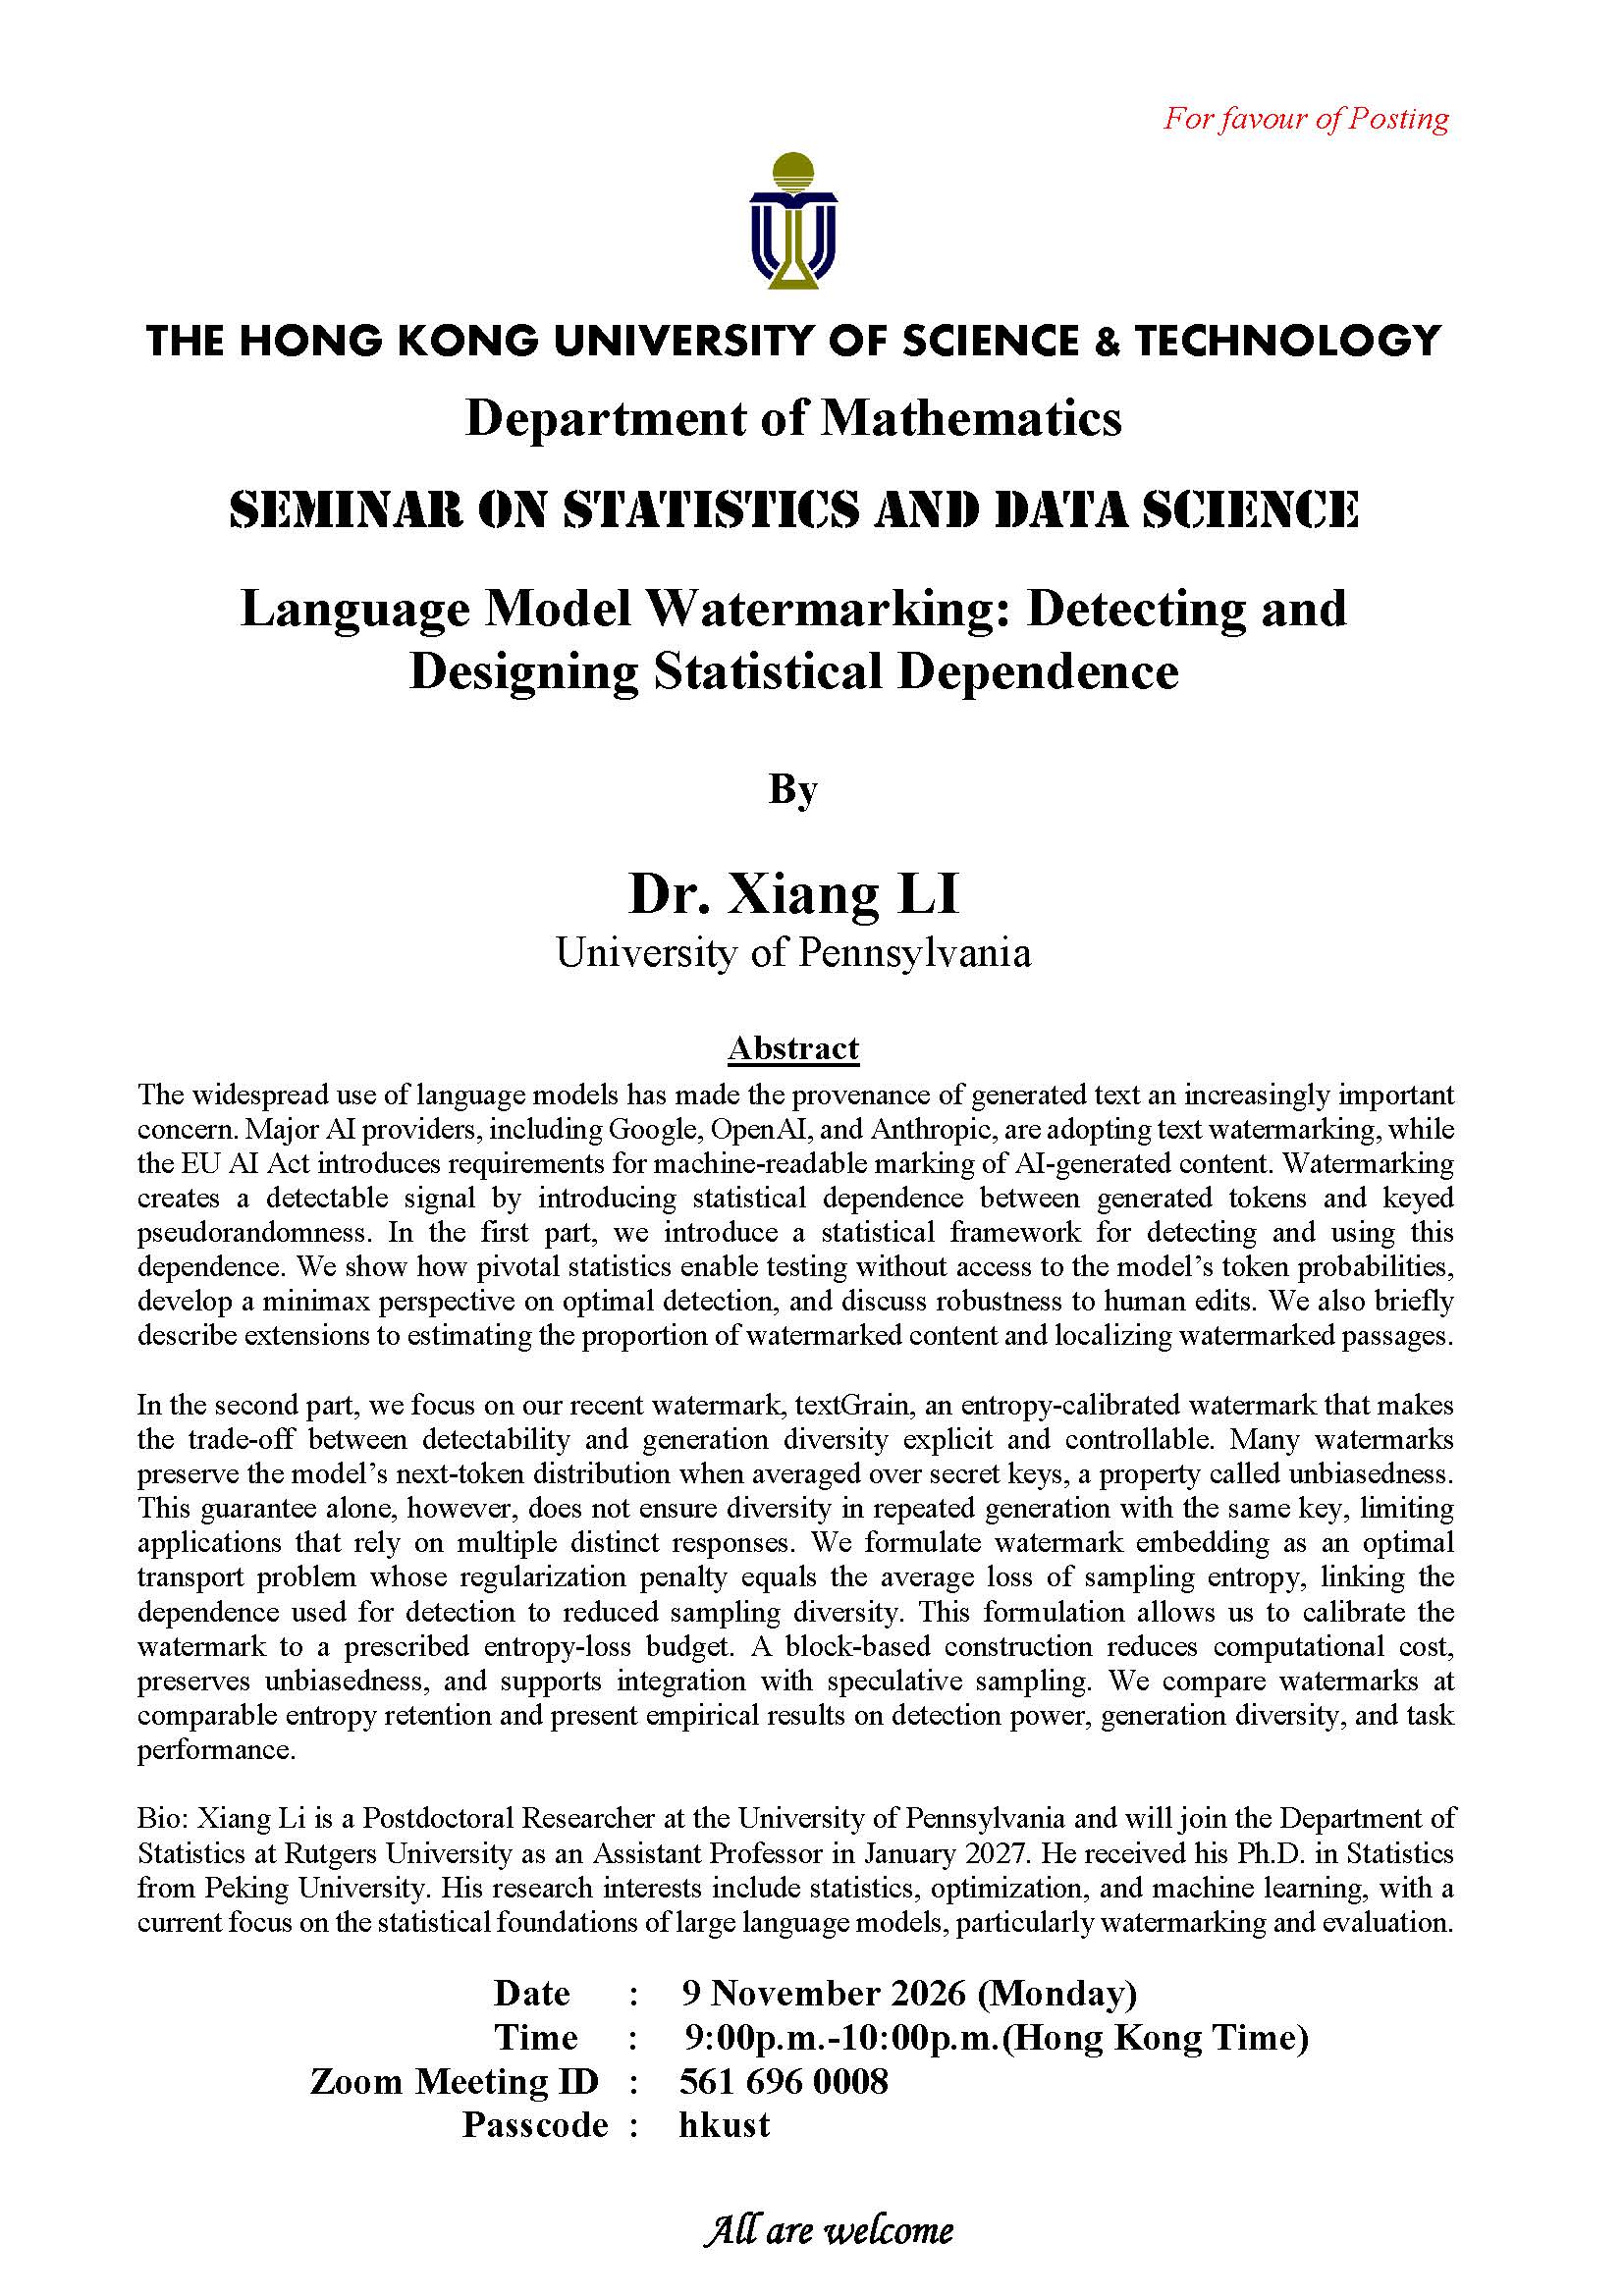
- Title: Language Model Watermarking: Detecting and Designing Statistical Dependence. [ poster ] [ slides ]
- Speaker: Dr. Xiang LI, University of Pennsylvania and Rutgers University.
- Abstract:
The widespread use of language models has made the provenance of generated text an increasingly important concern. Major AI providers, including Google, OpenAI, and Anthropic, are adopting text watermarking, while the EU AI Act introduces requirements for machine-readable marking of AI-generated content. Watermarking creates a detectable signal by introducing statistical dependence between generated tokens and keyed pseudorandomness.
In the first part, we introduce a statistical framework for detecting and using this dependence. We show how pivotal statistics enable testing without access to the model’s token probabilities, develop a minimax perspective on optimal detection, and discuss robustness to human edits. We also briefly describe extensions to estimating the proportion of watermarked content and localizing watermarked passages.
In the second part, we focus on our recent watermark, textGrain, an entropy-calibrated watermark that makes the trade-off between detectability and generation diversity explicit and controllable. Many watermarks preserve the model’s next-token distribution when averaged over secret keys, a property called unbiasedness. This guarantee alone, however, does not ensure diversity in repeated generation with the same key, limiting applications that rely on multiple distinct responses. We formulate watermark embedding as an optimal transport problem whose regularization penalty equals the average loss of sampling entropy, linking the dependence used for detection to reduced sampling diversity. This formulation allows us to calibrate the watermark to a prescribed entropy-loss budget. A block-based construction reduces computational cost, preserves unbiasedness, and supports integration with speculative sampling. We compare watermarks at comparable entropy retention and present empirical results on detection power, generation diversity, and task performance.
- Bio: LI, Xiang is a Postdoctoral Researcher at the University of Pennsylvania and will join the Department of Statistics at Rutgers University as an Assistant Professor in January 2027. He received his Ph.D. in Statistics from Peking University.
His research interests include statistics, optimization, and machine learning, with a current focus on the statistical foundations of large language models, particularly watermarking and evaluation.
|
Y.Y. |
|
| 11/16/2026, Mon |
Lecture 10: An Introduction to Reinforcement Learning with Applications [ slides ]
[ Reference ]:
- Google DeepMind's Deep Q-learning playing Atari Breakout:
[ youtube ]
- To view .ipynb files below, you may try [ Jupyter NBViewer]
- Deep Q-Learning Pytorch Tutorial: [ link ]
- A Tutorial of Reinforcement Learning for Quantitative Trading:
[ Tutorial ]
[ Replicate ]
- FinRL: Deep Reinforcement Learning for Quantitative Finance
[ GitHub ]
- Reinforcement Learning and Supervised Learning for Quantitative Finance: [ link ]
- Prof. Michael Kearns, University of Pennsyvania, Algorithmic Trading and Machine Learning,
Simons Institute at Berkeley [ link ]
|
Y.Y. |
|